FuriosaAI Takes Aim at Inference
2026-10-15
Efficiency is FuriosaAI's wager. The chip developer is pitching an energy-efficient alternative to Nvidia for inference, the process through which trained artificial intelligence models produce answers rather than learn from training data. That distinction matters commercially. As businesses put models into service, each request creates another computing expense, giving specialized processors an opening that raw computing speed alone cannot explain.
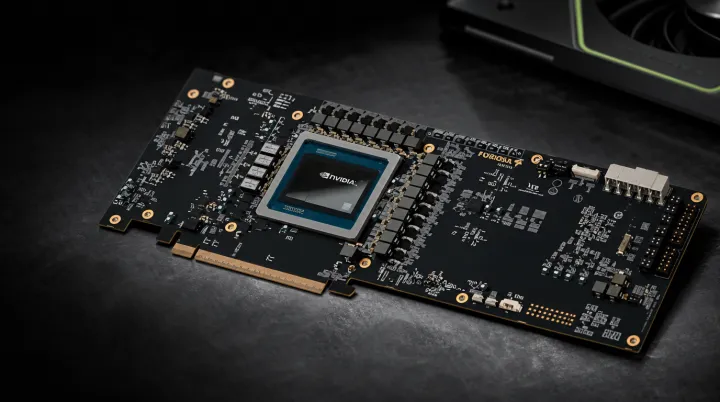
Specialization carries a price. Inference relies heavily on matrix multiplication and memory bandwidth, because processors must repeatedly calculate with model parameters and move those parameters between memory and computing units. Power is only part. A chip that consumes fewer watts must also deliver sufficient throughput at acceptable latency, while accommodating the models and software that customers actually use. Benchmarks need careful reading. Without comparable workloads, model accuracy, batch sizes and system configurations, an efficiency claim cannot establish whether switching hardware will reduce the cost of serving an answer.
Nvidia's defense extends beyond silicon. Its CUDA software ecosystem and established developer tools make replacement a question of engineering effort as well as procurement, leaving challengers to prove that savings justify migration. Buyers purchase working systems. FuriosaAI's opportunity therefore rests on converting its efficiency pitch into dependable deployment, where software compatibility, utilization and support can matter as much as the processor itself. The market need not produce a single winner for a specialist to earn business from suitable workloads. The contest reaches the meter. Behind every fluent answer sits an electricity bill, indifferent to the name stamped on the chip.
Loading...